Most businesses measuring AI search are staring at a number that can go up while the business outcome gets worse.
Here’s the problem many people are overlooking. A mention, a citation, a recommendation, and an actual customer outcome are not the same thing. Most people track them like they are.
Ahrefs dug through 1.4 million ChatGPT prompts and found that a source can get pulled into the retrieval process without ever surfacing as a visible citation. The AI used you. The reader never saw you.
This is exactly why I keep saying being retrieved is not the same as being preferred. Search Engine Journal additionally pointed out that a brand’s AI visibility score can climb while its clicks and real business outcomes move in the opposite direction.
So you can win the visibility report and still lose the customer. The score going up tells you very little on its own.
The missing step is retrieval
Here is the twist I think most AI visibility reports still miss. A recent Search Engine Journal article walks through a simple way to test whether a specific page is even making it into an AI retrieval pipeline.
The idea is straightforward: give an AI search system a distinctive passage from a page and see whether it can return and correctly attribute that page.
If it can’t, your problem may have nothing to do with “GEO content” at all. The page may be hard to discover, blocked by bot security, poorly crawlable, noindexed, canonicalized elsewhere, or have some other problem.
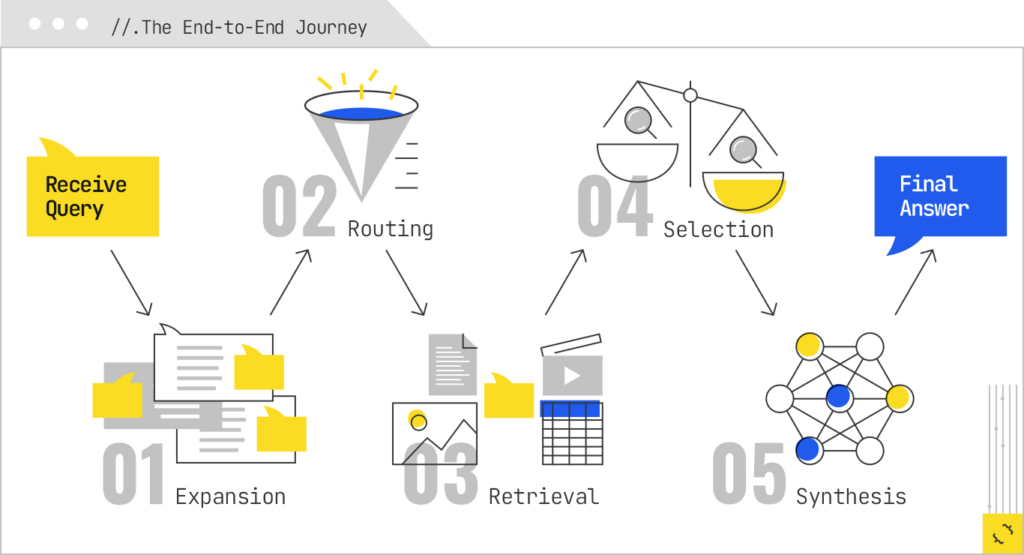
First, can the system find the right page or passage?
Then, does it cite your site?
If it mentions you, does it actually understand what you do and why someone would pick you over the alternative?
And when someone asks AI who’s best for the job, are you the clean recommendation, or the one that comes with a “but”?
And finally, does any of that produce a qualified visit, call, appointment, demo, or sale?
Those are very different stages. A single visibility percentage can oversimplify them by collapsing all of them into one number.
What I would actually measure
I would start with the 10 or so pages closest to revenue. Test whether AI systems can retrieve them. Then run the buying questions your real customers ask, and compare how the models describe you with how you actually want your business positioned.
Look for recommendation language, competitor preference, caveats, and whether your site is being cited.
Then connect that back to the part that really pays the bills. That’s right, qualified traffic and conversions.
This is the standard we apply to our clients at SEO Rank Media. Our verified client reviews across multiple platforms speak for themselves.
One client specifically reported roughly 220% growth in targeted organic traffic and a 36% increase in qualified leads, along with stronger visibility in AI search.
I care about the improvement in AI visibility, but I care much more about qualified-lead improvement. That’s the difference between measuring attention and measuring whether the attention is useful.
So if your AI visibility score is going up, great. My next question would be what happens after the mention, and if sales are not increasing, why?
If you want to discuss further, schedule a call with me and I’ll help you look at the chain from retrieval through recommendation and conversion. The goal is not another shiny AEO report. It’s finding the gap closest to revenue and deciding what’s actually worth fixing.
How brands can earn AI visibility, selection, and agentic action
There are two distinct things happening in AI search, and I think most people are blurring the lines between them.
First, there’s AI search optimization. That’s about being found, understood, cited, and picked when someone asks an AI a question your brand could answer. Second, there’s agentic optimization. That’s different. That’s about helping an AI actually finish a task on your site, whether that’s booking something, buying something, or filling out a form.
Both matter. Neither is optional anymore. That’s the whole game in a nutshell. Get retrieved, get understood, get chosen, and make sure the path after that doesn’t fall apart.
Key takeaways:
AI search recommends, agentic search acts, and your site needs to be ready for both.
SEO fundamentals are still the base everything else should be built on.
Clear facts, direct answers, and credible mentions drive both retrieval and preference.
Semantic HTML and stable forms make your site usable for agents, not just humans.
Measure real business outcomes, not just how often you get cited.
What Is the Difference Between AI Search and Agentic Search?
Here’s the real difference between AI search and agentic search. It comes down to what happens after the system finds the information.
AI search retrieves sources, weighs the evidence, and hands you a recommendation. Agentic search doesn’t stop there. It can include navigating a site, filling out a form, checking if something’s in stock, requesting a quote, or knocking out whatever task actually needs doing. In this way, it serves as the user’s “agent”.
A few ways to think about where each approach draws the line:
Traditional SEO asks one question: can a human or machine even find this page?
AEO and GEO push further: can the machine understand the content, retrieve it, cite it, and actually prefer this brand over the next one?
Agentic optimization goes a step beyond that: can the machine get the user’s goal accomplished with this specific business, not just talk about it?
I got into some of this with Tory Gray, an SEO strategist I interviewed recently. I didn’t want another surface-level chat about ranking in ChatGPT. We dug into rendering, prompt tracking, server logs, the standards still taking shape, and what agents might actually start doing on a website soon.
Tory made a point that I agree with. AI search is mostly SEO with a few new channels bolted on. Agentic work is a different animal entirely. The bots are different, the actions are new, the requirements keep shifting, and nobody has measurement fully figured out yet.
I agree with her on that one.
Why Does Agentic Search Matter Now?
Here’s what I’m seeing right now, and I think most people are misreading it.
Google Agent is Google’s named fetcher for Google-hosted agents that can navigate the web and act on a user’s behalf. That’s it. It’s not a product name you’ll see marketed anywhere, and it’s definitely not Googlebot. Googlebot builds the search index. Google Agent represents something different: a live task being carried out on someone’s behalf in real time on behalf of the user. And as I mentioned earlier, this is agentic search.
I’ll be straight with you, it’s not a complete picture either. Google hasn’t mapped this identity to every agentic product it runs, so we’re looking at part of the activity, not all of it.
Project Mariner as a standalone experiment is done. But don’t mistake retirement for disappearance. That browser automation work didn’t vanish; it just moved. You’ll find it now inside Gemini Agent and baked into the agentic features showing up in AI Mode. Chrome Auto Browse also now delivers the same broader class of browser automation directly inside Chrome.
If you care about search strategy, AI Mode is where I’d focus. Google has said the action layer there can pull together live web browsing, partner integrations, the Knowledge Graph, and Google Maps all at once.
On my end, I keep the traffic separated because lumping it together tells you nothing useful. Googlebot, OAI SearchBot, Claude SearchBot, and PerplexityBot are your search and indexing crawlers, plain and simple.
ChatGPT User, Claude User, and Perplexity User are different; that’s user-directed retrieval: someone asked for something specific, and the bot went and got it. Then you’ve got Google Agent and signed ChatGPT Agent traffic, which can mean actual operation on a site. And local browser agents are the trickiest of all, because half the time they just look like normal human traffic.
Here’s why any of this should matter to you. A brand can do everything right. Rank well, get recommended by the AI, check every box, and still lose the customer at the finish line. Why? Because the agent hit a firewall challenge, or got stuck on a CAPTCHA, or timed out, or ran into a broken form, or the page was labeled in a way the machine couldn’t parse. The visibility battle isn’t the only battle anymore. The second question is whether the path from recommendation to action actually holds up, and it needs to hold up for machines just as much as it does for people.
How Should You Optimize for AI Search?
I recommend starting with the pages closest to revenue. The service and product pages that actually drive decisions. That kind of page has to answer the main question immediately, make it obvious who it’s for, walk through what working together looks like, and handle the objections buyers already have in their head before they even ask.
Here’s the part most people miss. Every section should ideally give its answer right away, not three sentences in, after some warm-up. AI systems usually pull a single chunk of a page, not the whole thing. If that chunk can’t stand on its own, it never gets used, no matter how good the rest of the page is.
Once the on-site work actually holds up, I go look everywhere else. Because that’s really where trust gets built or lost.
Getting retrieved is step one. Getting picked is a completely different issue, and it often comes down to whether the evidence outside your website backs up what you’re claiming on it.
How Should You Make Your Website Agent-Ready?
Here’s what I actually do when I audit a site for agent readiness. I don’t click through a few pages and call it good. I run the entire flow start to finish, whether that’s a quote, a booking, a checkout, an application, or just a basic contact form. That’s where the real problems live, not in some surface-level page review.
I check the real links, real buttons, real labels, real inputs, and real select controls. Every interactive element needs a name a machine can actually read, and every label has to be properly tied to its field. This isn’t optional anymore. Chrome has said flat out that agents rely on the accessibility tree to understand a page, so accessible names, stable layouts, and the emerging WebMCP support matter more than most people realize right now.
Rendering is where things tend to fall apart. If your JavaScript is fragile, some retrieval systems only see half the page, sometimes an empty shell and nothing else. And if your layout shifts late, an agent can click the wrong thing simply because a button moved half a second too late. So my audit covers all of it. The raw HTML response, what actually renders, the accessibility tree, layout shift behavior, server responses, and whether the whole workflow completes cleanly from start to finish.
Example: An Agentic Local-Service Journey
Let me walk through a real example, because I think this is where people get the mental model wrong.
Someone asks an AI assistant to find a reputable roof cleaner near Charleston, one that does soft washing, and they want an estimate this week. The first job for the system is just finding businesses that actually fit that ask. That part is SEO and AEO. It’s pulling from search results, maps, service pages, reviews, whatever signal exists out there.
Then comes the sorting. Out of everything it found, which business actually matches what this person needs? Location, method, reputation, can they even get there this week, whatever proof exists that this company is the real deal. That’s not regular SEO doing the work anymore. That’s AEO, relevance optimization, and maybe conversion rate optimization deciding who earns the pick.
Here’s the part most people miss, though. Even after a brand wins that comparison, even after it’s clearly the best match, there’s still a third job waiting. The system has to go to that website and actually submit the estimate form on the person’s behalf. This third job is where agentic search comes into play.
And I’ve watched good businesses lose leads they already won right here. The form doesn’t fill in correctly. It hits a bot detector and stalls. The fields are vague or mislabeled, so the system can’t figure out what goes where. All that effort getting found and getting picked, and it falls apart because the technical door never opened.
Which Emerging Technologies Deserve Attention?
I want to flag a few emerging technologies worth watching, because they’re tied to real business use cases instead of just being noise. WebMCP, mentioned earlier in this article, is the one I’m paying closest attention to. Chrome describes it as a proposed standard for exposing structured website tools to AI agents. So instead of an agent fumbling through a form field by field, guessing what goes where, it could just call a defined tool request_estimate and skip straight to the outcome.
That said, WebMCP is still in the early days. I wouldn’t commit serious engineering time to it unless you’ve got a repeatable, valuable action that actually justifies the build.
The same logic applies to llms.txt. It’s not a proven ranking factor, but it can help AI agents understand and navigate through a website, which is where I see potential value.
Google’s Open Knowledge Format is a different thing entirely. It structures portable knowledge in Markdown with metadata, but it’s not a universal standard for public search or website actions. People blur these together, and it just creates confusion.
How Should You Measure AI Search and Agentic Performance?
I measure AI search and agentic performance across behavior, visibility, and business results. Tory and I got into this exact model because citations alone don’t prove anything. A brand can get cited all day and still not see a dime of value from it.
Start with the logs. Go into your server and CDN logs and see which bots and agents are actually touching your assets, and whether they’re getting blocked with 403s, throttled with 429s, timing out at 499, or hitting 5xx errors. When speaking about agentic bots: Google Agent and verified, signed ChatGPT Agent traffic deserves first-class treatment in your metrics. But here’s the blind spot nobody talks about enough. Claude in Chrome, Browse with Copilot, Perplexity Comet, and a growing pile of custom agents often just look like regular browser traffic. You won’t always know an agent touched your site unless you go looking for it.
From there, track a stable set of high-intent prompts over time. Watch for mentions, citations, which sources get selected, whether the facts are even accurate, and your share of voice against competitors. This is directional. It’s a sample, not a real record of what real customers are doing across every possible query.
Then tie it all back to something that actually matters. Qualified traffic, assisted conversions, leads, and revenue. I said this in an interview and I’ll say it again. I care about revenue. I care about leads. I care about driving real business value from this work. Visibility is a leading indicator; it tells me something is working before the revenue shows up, but it’s never the final score.
Which Tools Help Research and Measure This Shift?
There’s a plethora of new tools flooding the market right now, and honestly, most of them do very specific jobs. Exa pulls relevant webpages and passages for AI systems. DataForSEO gives you the bigger picture on SEO and AEO data. SerpApi shows you exactly what a search interface is returning at a given moment. Different tools, different purposes.
Here’s what I’ve learned running SEO Rank Media. The tool itself isn’t the point. What matters is whether it gets my clients the result they actually need. So we use all of it, plus our own internal AI and automation, to pull in the kind of information that actually moves the needle.
At the end of the day, I’m not trying to sell anyone on a piece of software. I’m building a strategy around the business in front of me, and I’ll pull whatever tool fits that job. That’s the whole approach. Customize first, then figure out which tools get you there.
What Should You Do Next?
Preparation for agentic search comes down to the path from discovery to recommendation to action, and you need to strengthen every step of it.
Start with the technical SEO foundation. Then make your key claims answer-ready, so an AI can actually pull them out and use them without guessing. After that, go audit how AI tools are already describing your brand. You might be surprised, and not always in a good way. Last step, and the one people skip, is testing whether an agent can actually complete a real customer journey with you, start to finish.
If you want a real baseline instead of a guess, I offer an AI visibility and agentic readiness audit. Reach out to me, and I’ll show you exactly where your brand is getting retrieved, where you are losing preference to someone else, and where technical friction is quietly blocking your next round of qualified leads.
Google’s new OKF is hot off the press. There’s a lot of hype around it, so let me explain what it is and why it may matter to you.
An OKF “bundle” is a directory of Markdown files. Each file explains one concept, such as a product, service, policy, or process, and includes a small block of structured information.
The files can link to one another, creating a connected map of what a business consists of.
That map, at least in theory, could make information about a business easier for AI systems to retrieve, connect, and understand—provided the bundle is accessible to those systems.
Why does that matter?
Before the search and retrieval systems behind Google, ChatGPT, Claude, and other AI platforms can explain your business or recommend it to a potential customer, they must first find, read, interpret, and connect information about it.
Making your business easier for these systems to understand is an important part of relevance optimization for the modern search environment.
Some AI systems use retrieval-augmented generation, or RAG, to locate relevant information and incorporate it into a response.
Others use AI agents—software assistants that can decide what to investigate next, compare multiple sources, and complete a sequence of tasks on a user’s behalf.
OKF is designed to help systems like these consume structured knowledge. Because it uses clearly labeled, linked, plain-text files, it can make relationships between products, services, policies, processes, and other concepts easier to interpret.
That could become useful as more prospective customers turn to Google, ChatGPT, Claude, and similar tools to research products, compare services, and identify businesses.
If these systems can access and correctly understand what your company offers, whom it serves, how its services connect, and why it is credible, your business may be better positioned to appear in relevant research and recommendation workflows.
But OKF Is Not a New SEO Requirement
This is where I’d slow down a bit and make sure we’re making a sober, realistic assessment.
OKF came from Google Cloud’s data and analytics organization, not the Google Search team.
Google has not announced OKF as:
A ranking factor
An AI Overview requirement
An AI Mode optimization feature
A crawler directive
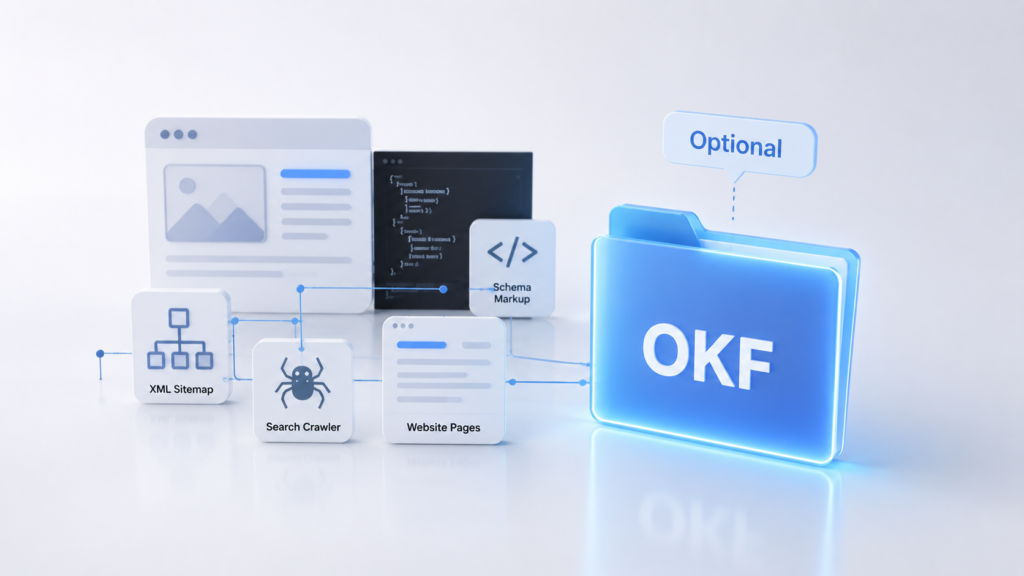
A replacement for schema markup, XML sitemaps, or normal web pages
Does that mean OKF is irrelevant? Absolutely not.
In fact, one could argue that one should not expect Google to tell the whole truth about how to manipulate its systems to rank and recommend you more.
But the fact remains that you should treat any claim that publishing an OKF folder will improve rankings or earn more ChatGPT and Google AI citations as speculation.
This may become a confirmed future use case, but it has not been proven.
Does Your Business Need OKF?
For most small and midsize businesses, my answer today is:
Probably not yet.
A local contractor with weak service pages, inconsistent business information, poor reviews, and indexing problems will not fix those issues by creating an OKF bundle.
The same applies to a professional-services company whose website does not clearly explain who it serves, what it does, where it operates, or why a buyer should trust it.
OKF becomes more relevant when a company:
Has large amounts of valuable knowledge spread across several systems
Is actively developing internal or customer-facing AI agents
Maintains extensive technical documentation, datasets, APIs, or product information
The Bigger SEO and AEO Lesson
Although most businesses probably don’t need to implement OKF today, they should pay attention to what it represents.
My larger takeaway, which hopefully you can also recognize, is that search has moved beyond finding pages that mention the correct words.
AI systems increasingly need to retrieve specific facts, understand how those facts relate, determine which version is current and reliable, and assemble the information into an answer or action on behalf of users.
Your competitive advantage is therefore becoming less about publishing the highest number of pages and more about maintaining the clearest, most reputable, best-connected source of truth.
If you want the short version, here’s what I’m seeing right now. Local SEO is still very much alive, but the way people discover and choose local businesses is changing. Google is moving toward a more conversational, AI-engine experience, so it’s not enough to just rank anymore. Your business also needs to be easy for Google to understand, easy for AI systems to summarize, and easy for real people to trust. I recently sat down with Darren Shaw from Whitespark, and the conversation reminded me why local SEO is still one of the most valuable parts of search.
Darren has been in this space long enough to see local search evolve from simple map pack tactics into a much more sophisticated system of proximity, relevance, reviews, business data, and now AI recommendations. That kind of perspective matters to me. A lot of people in SEO get distracted by the latest acronym or trend, but what I appreciate about Darren is that he has seen enough cycles to know what actually holds up over time.
The main takeaway of the conversation was pretty simple. AI is changing the way people experience search, but it is not replacing strong local SEO fundamentals. If anything, it is making them even more important.
The local search interface is changing
The local search interface is changing because people are no longer limited to short keyword searches like “plumber near me” or “dentist Dallas.” They are asking longer, more specific questions. They want recommendations based on urgency, preference, trust, location, availability, and context.
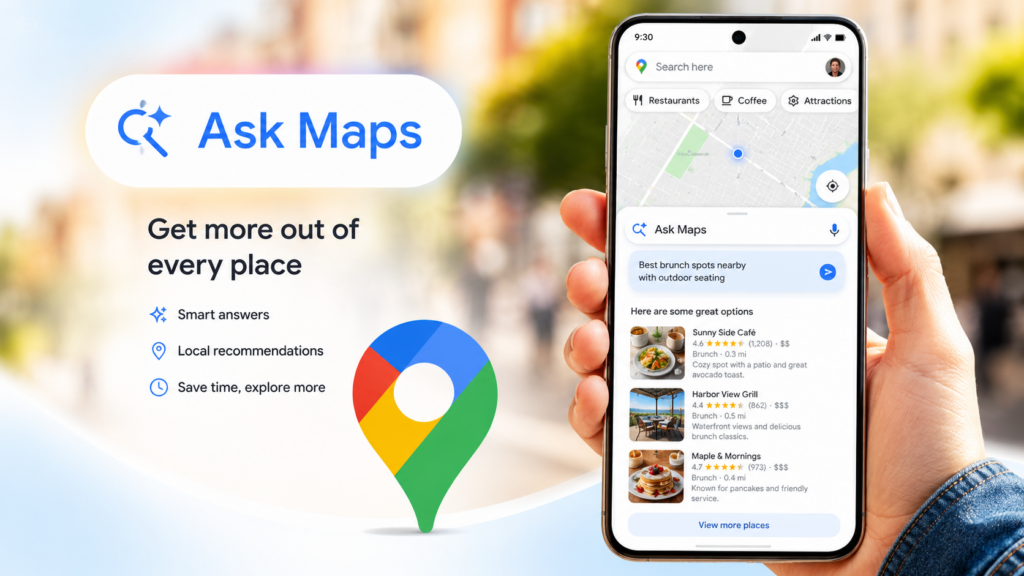
That changes the job of local SEO. For a long time, local SEO was mostly about ranking in the local pack for short keywords. I still think that matters. I just don’t think it tells the whole story anymore. In an AI search environment, the bigger question is whether the system understands your business well enough to recommend it in the right situation. That’s why I think Google’s Ask Maps feature matters. Google is turning Maps into a Gemini-powered conversational experience where people can ask real-world questions about places and get personalized recommendations based on Maps data. To me, that’s a pretty clear signal. Maps is becoming more than a directory. It’s becoming an AI search layer that helps people make real-world decisions.
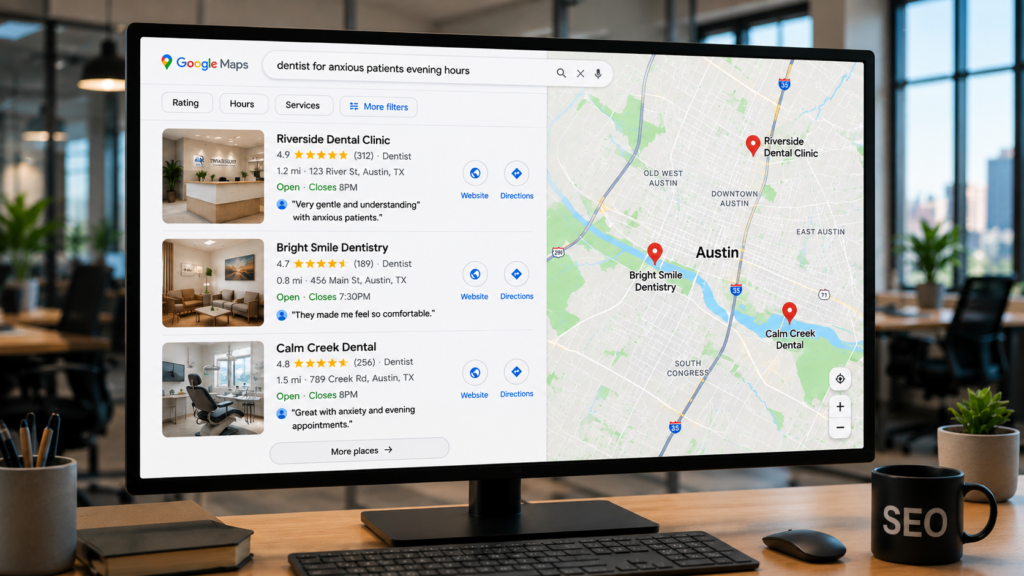
When I look at a search like finding a nearby dentist who is good with anxious patients and offers evening appointments, I see a very different kind of intent than a simple “dentist near me” search. The practice that wins that query is usually not just the one closest to the person searching. It is the one with the clearest service information, the strongest reviews, useful supporting content, and enough trust signals that Google feels confident recommending it. That’s where local SEO is headed.
Local SEO was never just about ranking
I never viewed local SEO as just a rankings play. A local business does not win because it shows up. It wins when someone chooses it. Rankings give you visibility. Selection is what turns that visibility into revenue.
That’s where I see a lot of businesses get stuck. They obsess over where they appear and ignore how they look when a real customer starts comparing options. You can rank well and still lose the lead if your Google Business Profile feels thin, your reviews do not build trust, your photos look outdated, or your service details do not answer the question the buyer actually has. That matters even more now because AI-driven local search is not just about retrieving businesses. It is comparing them. It is summarizing them. It is trying to decide which option looks most useful for the person searching. So when I look at local visibility, I want a business to be built for both retrieval and preference. Retrieval means Google can find it and understand it. Preference means the system has enough confidence to show it as the better fit. That’s the standard I care about.
Reviews are one of the strongest trust layers in local SEO
I think reviews are one of the strongest trust layers in local SEO because they influence both rankings and conversions. Darren made that point clearly in our conversation, and I agree with him completely. A lot of business owners still think about reviews as reputation management. That is part of it, but it’s not the whole story. Reviews are also content. They capture the real customer experience in natural language. People talk about services, staff, neighborhoods, problems, outcomes, wait times, pricing concerns, and the reasons they chose that business in the first place. That kind of language helps customers decide, but it also helps search systems understand the business at a deeper level. If patients keep saying a dental office is great with nervous patients, that is a meaningful signal. If homeowners keep mentioning emergency roof repair after storms, that matters too. If restaurant customers keep bringing up gluten-free options, fast service, parking, or atmosphere, that gives useful context. I think this matters even more in AI local search because the query is getting more conversational. People are not just searching for a category anymore. They’re looking for the right fit.
Review recency matters more than most businesses realize
Review recency matters more than most businesses realize because customers and search systems both care about what’s happening now. A business with a large review count but no recent activity can look stale. A business with fewer total reviews but consistent new reviews can look active, trusted, and relevant.
That does not mean businesses should chase reviews in a sloppy or aggressive way. It means review generation should become part of the operating process. Ask at the right time. Make it easy. Train the team. Use a simple review link or QR code when appropriate. Follow up naturally. Keep the process tied to real customer experience. The mistake is treating reviews like a one-time campaign. Reviews should be a steady signal that the business is active, trusted, and still delivering. That is especially important in competitive local markets where every business claims to be the best. Reviews give buyers and AI systems a stronger reason to believe one business over another.
Your Google Business Profile has to be built like a conversion asset
I look at a Google Business Profile as a conversion asset, not a box to check. A lot of local buyers decide who to call before they ever spend much time on a website, so the profile itself has to help you win the click, the call, or the visit.
That is one reason local SEO has been more protected from AI disruption than pure informational SEO. If someone wants a definition or a basic how-to answer, AI may handle that without sending the user anywhere. But if someone needs a dentist, lawyer, plumber, med spa, restaurant, HVAC company, or roofer, they still have to choose a real business. And a lot of that choice happens inside Google. Your categories, services, products, photos, reviews, posts, hours, attributes, and business description all shape that decision. Some of those elements can affect rankings. Others do more of the conversion work. I care about both. I see too many businesses treat their Google Business Profile like a one-time setup task. They choose a category once, add a few photos, write a generic description, and move on. Then they wonder why competitors with stronger profiles keep getting the calls. That’s not how I approach it. If your profile is one of the main places customers compare you, it needs to be built intentionally and managed like a living visibility asset.
Categories can quietly make or break local visibility
Categories are one of those local SEO details that seem small until they start costing a business real visibility. I check them early because they tell Google what kind of business it is. If the primary category is too broad or just not aligned with the core offer, you can create a relevance problem before anything else even gets a chance to help.
I see this a lot. A law firm selects “law firm” when the better fit might be personal injury attorney, criminal justice attorney, or bankruptcy attorney. A dental practice might not reflect the services it actually wants to be found for, which means it can miss visibility for higher-intent searches tied to emergency dentistry, cosmetic dentistry, implants, or orthodontics. This is one of the first things I look at in a local SEO audit because it’s simple, but the impact can be significant. The primary category needs to match the main thing the business wants to be found for. Then the supporting categories, services, website content, reviews, and citations all need to reinforce that same relevance. That’s how I help close the gap between what a business offers and what Google understands.
Citations are still useful, but they are not a magic shortcut
Citations still matter, sure, but I don’t look at them as the shortcut they used to be in local SEO.
I think of them as trust and legitimacy signals. If a business only shows up on its website and Google Business Profile, that’s a pretty thin footprint. If the same business information shows up consistently across major directories, industry platforms, local sources, review sites, and other trusted third-party profiles, the business looks more established and easier to verify. I think that matters for Google. I also think it matters even more as AI systems take a bigger role in local discovery. What I would not do is push a business into hundreds of weak directories just to inflate the count. I would focus on building a clean, consistent presence in the places that actually matter. That usually means major business directories, relevant local sites, industry-specific platforms, review sources, and professional associations. The right mix depends on the business. If I am working with a lawyer, I am looking at legal directories. If it is a dentist, I want healthcare-related profiles. If it is a home services company, I am thinking about home services platforms, local associations, and trade directories. I am not after volume here. I am after confidence.
AI local search rewards complete information
AI local search rewards complete information because conversational searches need more context.
A short keyword search might only need a service and a location. But if someone is looking for the best emergency plumber nearby who can come out tonight and has strong reviews, the system has a lot more to evaluate. It has to understand the service, the urgency, the area, the availability, the review quality, and whether the business looks trustworthy. If your business does not communicate those details clearly, you are asking Google and AI tools to fill in the blanks. I do not like building marketing strategies around guesswork. I would rather feed the system better information. That starts with the basics. I want the website to answer real buyer questions. I want the Google Business Profile to list clear services. I want reviews that are recent and specific. I want citations to stay consistent. I want photos that build trust. And I want the content to explain who the business helps, what it does, where it works, and why someone should choose it. This is not about stuffing keywords into every sentence. It is about making the business easier to retrieve, understand, compare, and recommend. That is the difference I see between old local SEO and local SEO built for AI search.
Old SEO tactics are not enough by themselves
Old SEO tactics are not enough on their own anymore, especially in local search. Google is doing more than matching words. It’s getting more interpretive. It’s trying to understand the business itself, the context around the search, the evidence behind the claims, the sentiment around the brand, and whether the fit is actually right for that customer’s need.
That does not make traditional SEO useless. I still care about the fundamentals. Technical health matters. Crawlable pages matter. Strong content matters. Internal linking, backlinks, local relevance, and clean business data all still do real work. But now I see those pieces as support for something bigger. I am not just asking if a business can rank for a keyword. I am asking if Google would feel confident recommending that business for a specific situation. That shift changes how I approach local strategy. A generic service page is not enough. A thin Google Business Profile is not enough. A few old reviews are not enough. A list of locations without real local proof is not enough. If a business wants to win, it has to become the clearest and most credible answer for the situations it wants to own. That’s the work.
The biggest opportunity is fixing selection, not just visibility
The biggest opportunity is fixing selection, not just visibility. Most businesses want more rankings, but many of them are already leaking leads from the visibility they have.
If your profile gets impressions but few calls, that is a selection problem. If people click your profile but choose a competitor, that is a selection problem. If you rank locally but your reviews, photos, services, and website do not build confidence, that is a selection problem. This is why I don’t separate SEO from conversion. A stronger review profile can improve trust. Better photos can reduce hesitation. Clearer services can increase relevance. Better website content can support both users and AI systems. Stronger citations can reinforce legitimacy. A better Google Business Profile can turn more visibility into actual leads. That is how local SEO should be judged. Not just “Did rankings move?” The better question is, “Did the business become easier to find, trust, and choose?
Local SEO is getting more conversational, more personalized, and more influenced by AI, but the goal is still the same. I want the right customers to find your business, trust what they see, and feel confident choosing you.
What has changed is the standard. If you want to show up well in AI local search, your business needs complete information, recent reviews, accurate categories, clear service details, consistent listings, and content that answers the real questions people ask before they ever contact you. If you want a practical game plan, schedule a call with me. I’ll show you where your local visibility is leaking, what is keeping your business from being preferred, and which fixes I would prioritize first.
In a recent video interview, which you can find on my YouTube channel, Mitko asked me why it is that so many people say that “SEO didn’t work” for them.
A lot of businesses think search is supposed to reward them quickly just because they made changes, published content, or hired somebody to “do SEO.” That is not really how Google operates.
In fact, one of the biggest mistakes I see is people expecting fast, clean, obvious feedback from a system that is built to be cautious, suspicious of manipulation, and slow to hand out trust.
That is the frame I want people to understand.
I talk about this in the above recent YouTube video.
In the video, I talked about a Google patent that gets at this idea directly. The core point is that when changes are made to a document or a site, Google may not just cleanly move that page from old rank to new rank in a straight line. There can be a transition period. And during that transition period, the response can look delayed, negative, random, or just unexpected.
That part matters a lot.
Because what most businesses want is this: “I made the optimization, so now show me the reward.”
But what Google seems to be saying is closer to this: “You made a change. Fine. I am still going to watch it. I am still going to test it. I am still going to make sure I am not being manipulated.”
That is a completely different mindset.
And once you understand that, a lot of what confuses people starts to make more sense.
So when I look at Google, I do not look at it like some simple machine where you press a button and get a ranking. I look at it more like a system that is trying to protect itself. It wants to separate genuine value from manipulation. It wants to avoid being gamed. It wants to see what holds up.
And if that is how the system operates, then the businesses that win are usually not the ones chasing instant movement. They are the ones doing steady, credible, useful work long enough for trust to build.
That is the foundation.
And once you understand that foundation, thenext two shifts matter even more.
Why TurboQuant Matters More Than It Sounds
Now let’s build on that.
If Google is already operating from a place of caution and trust, then the next big question is how it gets better at understanding meaning, intent, and usefulness at scale. That is where TurboQuant gets interesting.
The simple version is that TurboQuant points to AI search getting much faster and more efficient at handling vector search. In plain English, that means better semantic understanding across huge amounts of information. It means systems can process meaning more efficiently instead of relying so heavily on simple term matching and slower methods.
What gets my attention here is not just the technical side of it. It is what it suggests about where search is going.
If Google gets faster at building and using these semantic representations, then it gets better at understanding what a person is actually looking for, not just what exact words they typed. It also gets better at pulling from a much larger pool of relevant information when deciding what to surface.
That raises the standard.
Because now it is not enough to just have a page that mentions the right terms. It is not enough to sound vaguely relevant. The system is moving more toward understanding whether your page actually helps with the need behind the query.
That is a big difference.
So when I look at something like TurboQuant, I do not see it as some separate “AI thing” over here and SEO over there. I see it as part of the same direction Google has been moving in for years. Better understanding. Better retrieval. Better intent matching. Better filtering of weak, generic, copycat content.
And that brings more pressure, not less.
You do not respond to this by pumping out more empty pages. You respond by making your content more answer-ready, more credible, and more tightly aligned with what real people and AI engines are looking for. You reduce fluff. You improve structure. You make your pages easier to understand. You make the value obvious.
That is what I think a lot of people miss when they hear about new search technology. They want a trick. They want a shortcut. But most of the time, what these changes really do is increase the reward for clarity and increase the penalty for weak thinking.
Why ChatGPT Just Became a Bigger Product-Discovery Surface
Now, here is the other shift brands need to pay attention to.
ChatGPT just became a more serious place for product discovery.
With the richer shopping experience that rolled out in late March, users can now begin to browse more visually, compare products side by side, and move through product consideration in a much more direct way inside ChatGPT itself. To me, that matters because AI visibility is not just about being cited anymore. It is increasingly about being considered.
That is a different stage of the journey.
A lot of brands are still thinking, “Do I show up?” But that is too basic now. The better question is, “When I do show up, can I be understood, compared, and chosen?”
Because that is where this is going.
If a person is using ChatGPT to explore products, compare options, and narrow decisions, then your visibility problem is no longer just a traffic problem. It is a retrieval and consideration problem.
Can the system pull in the right information about what you sell? Can it understand what makes your product different? Can it present your offer in a way that makes sense next to alternatives?
If not, you are leaking visibility at the exact moment somebody is trying to make a decision.
And this is where I think the connection becomes really clear.
Google’s operating logic has long been about resisting manipulation and trying to reward actual value over time.
New developments like TurboQuant suggest search systems are getting faster and better at understanding meaning and intent.
And now ChatGPT is becoming a stronger environment for product comparison and discovery.
Put all of that together, and the pattern is obvious.
The brands that win are not going to be the ones relying on shallow tactics, inflated claims, or messy pages that make people work to understand them. The brands that win are going to be easier to retrieve, easier to understand, easier to compare, and easier to trust.
That is the real shift.
So if I am looking at a brand right now, I am asking a few simple questions:
Is the message clear?
Is the offer easy to understand?
Is the content genuinely useful?
Are the pages structured in a way that helps both humans and machines?
When somebody compares this brand to alternatives, is there a strong reason to choose it?
Because search is not just a ranking environment anymore. It is becoming more of a retrieval, evaluation, and selection environment. And honestly, that has been building for a while. It is just getting harder to ignore now.
Be clearer. Be more useful. Be more credible. Be easier to understand. And stop expecting a trust-based system to behave like a vending machine.
That is the mindset shift.
And the businesses that make that shift early are going to be in a much better position than the ones still waiting for instant feedback from systems that aren’t designed to work that way.
If you want to win in AI search, you have to win two distinct, but related arenas. Getting retrieved and getting preferred.
I don’t treat AI visibility like a vanity ranking game. I care more about whether a brand is consistently pulled into the right conversations and preferred for high intent prompts.
The research supports that approach. The 2023 GEO study introduced Generative Engine Optimization and reported visibility gains of up to 40% from the right optimization methods.
First, your brand has to get retrieved. That means your site, brand, or page has to make it into the possible answer set. Then, once you are in the set, you have to get preferred. That second step is the re-ranking layer, where the model decides which option is the clearest fit for the user’s prompt. The 2025 E-GEO paper formalizes that same retrieval-plus-ranking framework.
That is why I don’t separate off-page SEO from on-page AI optimization. Off-page authority, mentions, citations, links, and digital PR help you get pulled in. Clear, well-structured, evidence backed content helps you get chosen once you are there.
I do not chase vanity rankings. Ranking for a head term like IT managed services might look good in a dashboard, but it tells me almost nothing about whether I am visible when a real buyer is actually close to choosing a provider.
People looking to purchase are not stopping at short category phrases anymore. They are asking long, detailed, constraint-heavy buying questions like:
“We run a 12-location healthcare group in Dallas and need a HIPAA-compliant IT provider that can manage endpoints, harden Microsoft 365, support audits, and help with compliance documentation. Who should we talk to?”
“Which Dallas managed IT companies can provide backup and disaster recovery with a one-hour recovery time objective, a 15-minute recovery point objective, and 24/7 incident response?”
“We need a managed cybersecurity partner for a multi-site medical practice that can handle SIEM, endpoint detection, phishing training, and policy documentation. Who actually does all of that well?”
This shift is not a theory anymore. Amazon says shoppers are already using Rufus to type natural-language questions, compare options, and ask granular product questions, while Bain found that 42% of large language model users already use these platforms for shopping recommendations.
In other words, I care less about whether I “rank #1” for a trophy keyword and more about whether search engines and large language models consistently understand that my brand is a strong answer for the high-intent situations my market actually cares about. That is what matters.
The process I use to increase AI visibility
My process starts with query selection, not page editing.
First, I identify the money prompts. These are the commercial, comparison-driven, bottom-of-funnel queries that reflect how people actually ask for help today. Then I expand those into related prompt variations so I can see the full intent map around the topic.
After that, I compare my page against competing pages and measure which page is most semantically aligned to the query. If my page is weak, I do not guess why. I fix the relevance gap.
Then I optimize at the chunk level.
Modern AI systems often retrieve and reuse sections, not entire pages. That is why I built an internal workflow that pulls strong content chunks, scores them against the target query, rewrites the best chunk into cleaner formats, and then re-ranks the outputs to identify the version most likely to be extracted and preferred.
In practice, the best version is usually the one that is easiest to scan, easiest to trust, and easiest to quote.
What I like about the 2025 E-GEO study is that it pushes the conversation beyond hype.
The researchers tested more than 7,000 realistic product queries, evaluated 15 common rewriting heuristics, and found that the best results came from a stable pattern rather than a gimmick. The content that rose tended to align closely with user intent, preserve factual accuracy, clearly differentiate itself, and present information in a format that is easy for the model to process.
I have had conversations in person and even on my YouTube channel with industry-leading colleagues like Nick Eubanks, Ross Simmonds, and Charles Floate, and even when the tactics vary, the same fundamentals keep coming up: build authority beyond your site, understand how people really search, and publish content that is clear enough to be reused in answers.
That is a big reason I believe AI visibility is not a trick. It is a discipline.
You need distribution. You need credibility. You need answer-ready content. And you need to stop measuring success with outdated vanity metrics that were built for a different search era.
AI visibility is not about gaming one prompt or chasing one keyword. It is about increasing the probability that your brand gets retrieved for the right conversations and is preferred when the model compares options.
Parent/head terms still matter as category and entity anchors for retrieval, internal linking, and query reformulation, but they do not deserve to be your primary measurement system for AI-era revenue visibility.
The KPI should be whether your brand is retrieved and preferred across the high-intent prompt set that real buyers actually use.
That means winning both arenas: off-page presence strong enough to get you into the set, and on-page structure strong enough to move you to the top.
That’s the process I use, and it’s the process I keep seeing validated by research, by testing, and by conversations with other people deep in this space. If you focus on those fundamentals, you stop chasing vanity and start building visibility that actually compounds. Schedule an introductory call with me today to discuss how we can do this for your brand.
A 2025 research study from researchers at MIT and Columbia University tested what actually moves content up in AI-generated rankings. Their big finding wasn’t “use this one weird prompt.” It was that repeatable, reliable gains come from a consistent structure: match user intent, stay factual, show clear differentiation, use evidence, and format content so it’s easy to extract.
I built a custom internal tool inspired by that study to help me (and my clients) turn messy, long-form information into “AI-ready” answer blocks that are more likely to be pulled and preferred in AI results. We’re actively expanding that tool to make it more comprehensive, and it’s already being used to guide client content.
I’ve spent the last couple of years watching the same pattern play out across industries:
Some brands get mentioned in AI answers… but show up as the third or fourth recommendation.
Others get pulled sometimes… but inconsistently.
And a few dominate because their content is the easiest to trust, quote, and rank.
That’s why I pay attention when researchers publish something that goes beyond opinions and actually tests what works.
The research team from MIT and Columbia University ran the study (E-GEO: A Testbed for Generative Engine Optimization in E-Commerce) to measure how answer engine rankings change based on how content is written. They used thousands of real-world shopping-style queries, rewrote product descriptions using different approaches, and tracked whether the rewritten versions moved up or down in AI rankings.
What I’m sharing below is the practical version of what matters, and how you can apply it whether you sell products or services.
The two-step reality: getting pulled vs getting preferred
Most brands only think about one part of the problem.
Step 1: Retrieval (getting pulled in)
This is whether your page, brand, or product even gets included as a possible answer.
Step 2: Re-ranking (getting preferred)
This is where the AI decides what’s “best,” “second best,” and so on.
The 2025 study focused heavily on that second step: once options are in the set, what makes one rise to the top?
If you’re investing in content for AI visibility, you want both:
● content that reliably gets pulled ● content that reliably gets ranked as the preferred option
What the researchers actually did (in plain English)
Here’s the simple version of the test:
They took 7,000+ real “what should I buy?” style posts from Reddit.
They matched each query to the 10 most relevant Amazon product listings using a semantic similarity method (basically, “meaning match,” not just keyword match).
They rewrote product descriptions using different prompt styles.
They measured whether the rewritten descriptions moved up in the AI’s ranking.
They then used a second model to iteratively improve the rewrite prompts until the rewrites performed better.
The purpose wasn’t to find a trick. It was to find patterns that hold up repeatedly across many queries and products.
That’s exactly what brands need right now, repeatable rules, not hype.
The most important practical takeaway
AI rankings reward content that makes it easy to confidently choose and easy to quote.
That’s why the winning patterns consistently included:
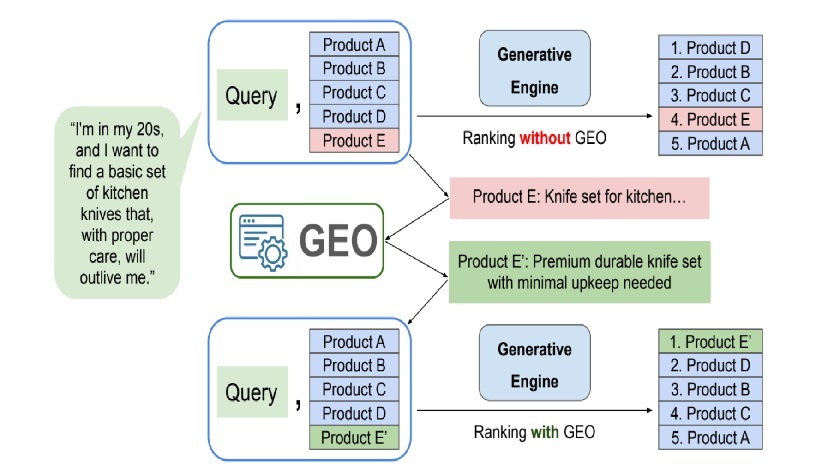
1) Clear intent match
The best-performing rewrites aligned tightly with what the user actually asked for, especially long, conversational queries with constraints.
Not “Knife set for kitchen.”
More like: “Premium durable knife set with minimal upkeep needed.”
That shift matters because it directly mirrors the user’s real goal.
2) Factual grounding
One of the most consistent themes was factuality. Keep claims accurate, avoid embellishment, and preserve what can be supported.
In real life, that means:
● don’t guess ● don’t inflate benefits ● don’t claim “best” without support
3) Clear differentiation (your “why us” without fluff)
Competitive positioning mattered, especially when it was expressed as concrete differences, not generic marketing language.
Examples:
● materials, specs, certifications ● what’s included vs not included ● warranty terms ● durability, maintenance requirements ● constraints the product/service is best for (and not best for)
4) Evidence signals
When you can back something up with data or reputable references, do it. Evidence helps the AI system “trust” the content and reuse it.
For service businesses, evidence can be:
● licensing and certifications ● documented process steps ● before/after metrics ● review volume and rating ● pricing ranges and what drives them
5) Scannable formatting
This one is huge, and it matches what I’ve seen in the wild. Content that’s easy to scan is easier for AI systems to lift into answers.
Headings, bullets, short blocks, ranges, and direct definitions beat long paragraphs every time.
What didn’t work as well
A lot of “internet advice” about AI visibility leans into tone or style:
● “Write like an ad” ● “Be super persuasive” ● “Tell a story” ● “Sound authoritative”
The study showed that these approaches can be inconsistent and, in some cases, can even hurt performance if they reduce factual clarity or drift away from the user’s intent.
The takeaway: style is secondary; structure and usefulness come first.
The custom tool I built (inspired by the study)
This study didn’t just confirm what I suspected; it gave me a structure I could build around.
So I built an internal GPT-powered re-ranking workflow inspired by the study’s re-ranking logic.
Here’s what it does in practical terms:
What my tool does today
I feed it a target query (example: “How much does carpet cleaning cost in Northern Virginia?”).
It ingests multiple content “chunks” pulled from top-performing pages on Google.
It ranks those chunks based on which one most directly and completely answers the query.
It rewrites the best chunk into multiple output formats, especially.
It re-ranks the outputs and recommends the version most likely to be extractable and preferred in AI answers.
In short, it helps us consistently produce content that is accurate, aligned with intent, and formatted for extraction, which is exactly what the study suggests is repeatably effective.
How we’re expanding it
Right now we’re expanding the workflow to be more iterative and mathematical about which content is most optimized. This will result in:
● content that more accurately reflects what AI engines reward ● stronger evidence handling ● consistency checks ● broader content formats
How we’re using it for clients
We’re already using this tool in our client work to:
● upgrade existing pages into AI-ready “answer-first” structures ● produce scannable sections that AI engines can quote cleanly ● reduce fluff while increasing proof and clarity ● align content with how people actually ask questions in AI tools
This is one of the ways we’ve been able to move faster while staying grounded and factual, because the tool forces discipline around intent, structure, and evidence.
Final thoughts
The 2025 MIT + Columbia E-GEO study supports something I’ve been emphasizing for a while:
If you want to rank well in AI answers, your content has to do more than “sound good.” It has to be the clearest match to the user’s intent, backed by facts, and formatted in a way that’s easy to extract and trust.
That’s why I built a tool around this and why we’re expanding it and using it actively in client content.
If you want your site to show up more often and be preferred in AI answers, request my free AI visibility checklist. I’ll review your site and tell you:
● what’s preventing AI engines from pulling your pages ● what’s keeping you from being ranked as the “top” recommendation ● which pages to fix first for the fastest impact
You can implement the changes yourself, or my team at SEO Rank Media can handle it for you.
Short version: llms.txt is a proposal, not a formal web standard. Some sites ship it; some AI tools and SEO plugins promote it. Google says you don’t need it to show up in AI Overviews or any other Google products.
But: …like any public .txt file, an llms.txt URL can be crawled and indexed, so in rare cases a bare, unstyled text page could show up in search instead of your real, designed page.
I know of someone who created a playful file called cats.txt to make a simple point: Google can index plain text files if they’re publicly accessible and discoverable. In other words, the name doesn’t matter; if it’s a .txt and reachable, it can show up in search, just like any other indexable file type.
If a text file is publicly visible on your site, search engines can list it, which you certainly don’t want. To prevent this, send X-Robots-Tag: noindex in the HTTP response (works for non-HTML files), and if you want to point search engines to the right page, add a Link: <https://your-page>; rel=”canonical” header. Here’s what a real plain-text doc looks like in a browser (the kind that could hypothetically rank if you don’t block indexing): https://developers.cloudflare.com/llms.txt.
Google’s documentation covers both the noindex response header for non-HTML resources and using an HTTP canonical header.
Below is a clear walk-through, first in plain English (with analogies), then the technical details and safest practices.
What is llms.txt?
llms.txt is a simple text file you put at example.com/llms.txt. The file lists or summarizes your most important pages in Markdown, so AI systems can more easily read and use your content. Think of it like a cheat-sheet menu for bots: “Here are the dishes you should try; here’s how to ingest or interpret them.” It’s inspired by robots.txt and sitemaps, but it isn’t an official protocol like those are, just a community proposal.
Today, there’s no universal adoption. A directory of live implementations shows many developer-tooling/docs sites experimenting, often paired with a bigger llms-full.txt that expands the content.
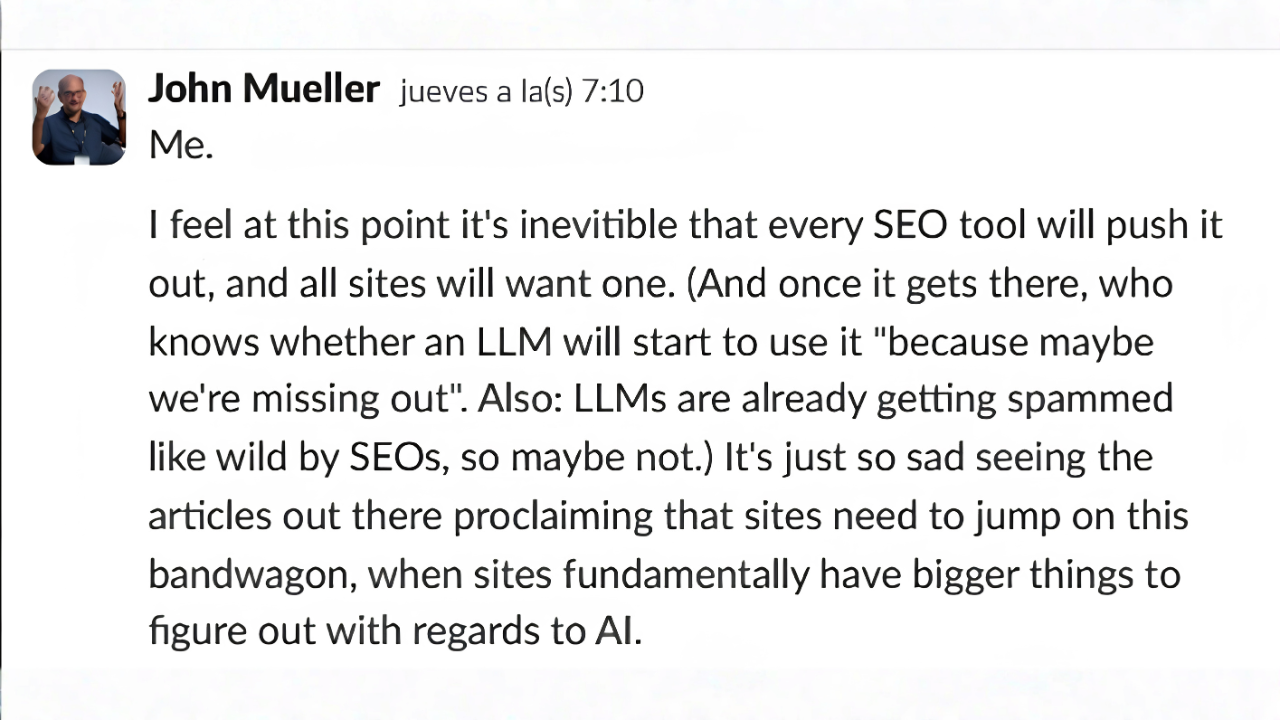
John Mueller / Google’s stance: In a conversation with Caleb and a few other colleagues, Google’s John Mueller made it clear what side of the debate he’s on. You don’t need llms.txt; the guidance is to keep following normal SEO practices.
Why is there a debate?
The “we don’t need this” camp
Google says it won’t use llms.txt for AI search results, so for many sites this is optional at best.
llms.txt isn’t a standard; support and behavior differ by bot. In other words, don’t expect consistent results.
The “we’re seeing activity in the wild” camp
Practitioners have shared examples and logs showing Google indexing llms.txt pages, alongside surges of bot hits when large platforms roll it out, because it’s just a public text file like any other.
That doesn’t prove Google uses llms.txt for AI search results. It only proves that public .txt files can be crawled and indexed, which Google’s docs have said for years.
A layperson’s guide to the technical bits
robots.txt vs noindex robots.txt is like a bouncer who tells certain crawlers not to walk certain halls. It doesn’t guarantee your URLs won’t show up in the search phone book (the index). Pages blocked in robots can still be indexed by URL if they’re linked elsewhere. If you truly don’t want a URL in the index, use noindex; that’s a separate rule delivered in HTML or HTTP headers.
X-Robots-Tag and canonical For non-HTML files like .txt, the right place to control indexing is the HTTP response header.
X-Robots-Tag: noindex = “don’t list this address in Google.”
Link: <https://example.com/page>; rel=”canonical” = “If you do need to reference this, use our public address here.” (Google supports canonical in the header for non-HTML formats.)
User-Agent/UA and why blocking by UA isn’t enough “UA” is the name badge a crawler shows at the door (e.g., Googlebot, GPTBot). You can write per-UA rules in robots.txt, and major AI vendors document their UA strings.
But name badges can be forged; to be sure a request is truly a vendor’s bot, verify by reverse-DNS/IP, not just the UA string. Cloudflare has even accused some AI crawlers of stealth crawling (changing badges and IPs).
“Cloaking” and dynamic rendering Serving different content to bots than to users is a slippery slope. Google considers cloaking a spam tactic when bots and users see materially different things. Google also deprecated dynamic rendering (bot-only HTML) as a long-term approach. If you want a bot-friendly version, keep the substance the same as what people see.
The cannibalization risk (and how to avoid it)
Imagine your llms.txt ranks for a branded query. A searcher clicks and lands on a wall of plain text with no design, navigation, or conversion paths. That’s the risk: poor UX and lost revenue. It’s not hypothetical; plain text files do get indexed, and practitioners have shown real examples of llms.txt and llms-full.txt pages in the index. We also showed an example earlier in this article.
Fix: keep llms.txt fetchable (so AI tools can read it) but non-indexable in web search with:
These are HTTP headers on the llms.txt response, not tags inside the file. This is the safest, standards-compliant way to prevent cannibalization while still letting crawlers pull your file.
If you still want to experiment: safest practices
1) Treat llms.txt as optional and experimental
Ship it only if it supports real goals. Keep expectations modest; it’s a proposal, not a protocol.
2) Prevent web-search cannibalization
Serve HTTP headers on llms.txt (and llms-full.txt if you publish one):
Think: “Please don’t list this file in the phone book. If you must reference something, here’s the main storefront.”
3) If you want to block certain AI crawlers elsewhere, do it the right way
In robots.txt, write rules per UA (e.g., User-agent: GPTBot). Vendors like OpenAI document their bot names.
For high-stakes data, verify IPs (reverse DNS) because UA strings can be faked. Google documents how to verify Googlebot; similar logic applies to others.
Be aware: some AI bots have been accused of ignoring robots.txt or crawling stealthily, so consider edge-level blocking if needed (WAF/CDN).
4) What to put in llms.txt (if you use it)
Link to canonical, public pages that you want AI systems to cite: FAQs, policies, product specs, pricing explainers, and key how-tos. Keep it concise; don’t dump the whole site.
5) Instrumentation & monitoring
A .txt file is just raw text. Web browsers don’t run code inside it, so you can’t drop a JavaScript analytics snippet (like GA/GTAG) into a .txt file and expect it to fire. Browsers only execute scripts when the content is served as a script/HTML type, not text/plain.
If you still want to see who’s fetching that file, look at your server or CDN access logs. Those logs list every request (time, IP, user-agent, URL, etc.), so you can count hits to /llms.txt even without JavaScript. Examples: Apache’s access log and Cloudflare Logs.
Watch Search Console: If a text file starts appearing in “Indexed,” revisit your headers. Google’s docs confirm indexing can occur even without crawling the content (e.g., when discovered by links).
6) Don’t block JS/CSS for Googlebot
If your SEO defense plan includes blocking scripts to hide unique content from AI, be careful: blocking JS/CSS broadly can break rendering in Google Search. If you must, target AI bots individually, not Googlebot
The bottom line (for decision-makers)
Not required:Google’s AI Mode doesn’t depend on llms.txt; normal SEO still wins.
Not a standard: It’s a proposal with uneven support. Useful for experimenting, especially for docs-heavy products; not a silver bullet.
If you try it, ship it safely:
Put it at the root.
Keep it short and link to your best pages.
Send X-Robots-Tag: noindex and, if helpful, a header canonical.
Keep content parity; avoid UA-based “special versions” that diverge.
If you must block certain AI bots elsewhere, use per-UA robot rules plus IP verification at the edge; be aware of stealth crawlers.
If you want a place to start, you can base your evaluation on current adoption (developer docs, ecosystems, and directories of live files) and any internal log evidence you have about bot hits to llms.txt. Then decide whether it’s worth maintaining a curated cheat sheet for AI or whether your time’s better spent doubling down on structure, internal links, and copy the proven levers. SEO Rank Media is among the leaders in the AI search conversation. Reach out to explore how we can set your brand up for the future.
There’s a common misunderstanding that large language models (LLMs) like ChatGPT or Gemini are replacing search engines. They aren’t. LLMs change how results are presented and explained, but the heavy lifting of finding, organizing, and ranking the web still belongs to search engines. In plain English: LLMs are the brainy librarians inside of a giant library; search engines are the library’s cataloging system that keeps track of every book, page, and shelf.
Below is a clear look at what each does, why they’re different, and why search is not only sticking around but also growing.
What search engines actually do (and why that matters)
Search engines run a huge, ongoing pipeline that works like this:
Crawl: Automated bots (“crawlers”) visit web pages and take notes on what they find.
Index: Those notes are stored in a gigantic, constantly updated catalog (the “index”).
Rank & Serve: When you search, the engine looks up the most relevant pages in that index and ranks them using complex algorithms.
Google’s own documentation lays out this crawl → index → rank process in detail. If you’ve never read it, it’s surprisingly readable and shows the scope and complexity behind what looks like a simple search box. directly;
You can’t browse Google’s index directly, it’s proprietary and unimaginably large. You query it. If you own a website, you can see your slice of the index in Google Search Console’s Page indexing report, which shows which of your pages are in or out and why. Microsoft offers similar visibility in Bing Webmaster Tools, including a Sitemap Index Coverage report that flags reasons URLs are excluded.
This is the invisible machinery of the open web. It’s what makes it possible to find new content minutes after it’s published and to keep billions of pages ordered enough to be useful.
What LLMs actually do (and what they don’t)
LLMs are trained to predict and compose text. They’re excellent at summarizing, explaining, reformatting, and reasoning over information they’re given. But there are two common misunderstandings:
LLMs do not maintain a live, internet-wide search index. The model itself isn’t crawling the web in real time or keeping a searchable catalog of every page as a search engine does. When LLMs need fresh facts, they typically consult a search engine index. Meaning they call a search engine service (UI or API). The search engine then queries its own index, returns ranked results, and the LLM fetches a few of those pages and combines them into the answer it generates for the user. Google literally calls this “grounding with Google Search.”
“Browsing” ≠ “crawling.” What we just described is called retrieval and summarization, not operating a global crawler and index. OpenAI’s newer “deep research” mode, for example, plans multi-step lookups and shows sources. Again: retrieval plus synthesis, not running its own universal web index.
This distinction matters because it explains why LLM answers can be hallucinatory. Without a high-quality retrieval step (i.e., search), an LLM is just “guessing” based on training data that could be outdated or incomplete.
That said, ChatGPT (the product of OpenAI) now runs a real web crawler called OAI-SearchBot and maintains OpenAI’s own web index so it can discover pages and show them as cited sources in ChatGPT Search. Which again proves this article’s point: you still need search infrastructure under the LLM.
The winning combo: grounding LLMs with search
The industry term for blending search with generation is Retrieval-Augmented Generation (RAG). In RAG, the system first retrieves relevant documents from a trusted source (like a search index or an enterprise knowledge base) and then generates an answer that cites those sources. Requiring the AI search engine to cite its sources can also dramatically reduce hallucinations. The original RAG research popularized this approach in 2020, and it’s now widely used.
You’ll see this philosophy in multiple places:
Google Gemini / AI Overviews: “Grounding with Google Search” pipes real-time search results into the model and returns answers with citations.
Vertex AI: Google Cloud’s guidance explicitly recommends grounding model outputs in verifiable data, via Search, RAG, Maps, and more, to reduce hallucinations.
The big picture: LLMs are the presentation and reasoning layer; search is the fact-finding and verification layer. You need both.
The library and the librarian
Think of the web as a giant library:
The search engine builds and maintains the card catalog (the index). It constantly scans new “books” (web pages), decides where they belong, and keeps the catalog current.
The LLM is the librarian who reads the relevant pages you point to and then explains them in friendly language, weaving them into a clear, direct answer. If the librarian is allowed to cite the exact books and page numbers, you can check the work.
When the librarian doesn’t check the catalog first and just “remembers” what books might say, mistakes happen. That’s why modern AI features emphasize grounding and citations.
“But aren’t people just using AI instead of Google now?”
Short answer: no. AI usage is up, and Google Search remains massive and growing.
Alphabet’s earnings releases and CEO remarks throughout 2025 show double-digit growth in Search revenue and healthy overall query growth, including a 70% year-over-year jump in Google Lens searches, much of which is incremental (i.e., additional to traditional text queries). That’s expansion, not replacement.
Independent financial reporting backs this up: multiple quarters in 2025 attribute Alphabet’s outperformance partly to strength in core search, even as AI features roll out alongside it.
It’s also useful to separate revenue from queries. Revenue grows when users stay engaged, and ads remain effective; queries grow when people search more, in more ways. Google has repeatedly highlighted growth in newer, multimodal behavior, like searching with your camera (Lens) or combined gestures, showing search is evolving rather than shrinking.
Why LLMs don’t (and shouldn’t try to) be search engines
Freshness at web scale: The public web adds and changes billions of pages. Keeping a comprehensive, deduplicated, spam-resistant, and continuously updated index is a specialized, infrastructure-heavy job. It’s what search engines were built for.
Transparency and provenance: When an LLM is required to cite sources, users can click and verify. This is standard in grounded systems like Gemini’s “Search grounding” and Vertex’s guidance. Purely generative answers can’t offer the same audit trail.
Governance and site control: Website owners monitor their presence in the index through Google Search Console and Bing Webmaster Tools, diagnosing why pages are in or out. That visibility is essential for a healthy open web and isn’t replaced by a model’s internal training data.
Commercial ecosystems: Search drives measurable, intent-rich traffic that businesses can analyze and optimize. That incentive structure sustains publishing and commerce broadly. The earnings results we’ve seen suggest these dynamics are holding, even as AI features appear in the interface.
What this means for everyday users
You’ll see more answers. AI summaries sit on top of search results and often include citations so you can dive deeper. Expect more multimodal options (speak, snap a photo, or draw a circle on your screen) that kick off a search behind the scenes.
Quality still wins. If you publish online, the fundamentals matter even more: sitemaps, clean site architecture, crawlability, canonical tags, structured data, and helpful content. Search engines need to index and rank your pages before an LLM can confidently cite them.
Trust but verify. AI answers can be great for speed and clarity, but when it counts, click through the citations. Even OpenAI’s more advanced research features emphasize sources precisely because models can still overstate or hallucinate details.
What this means for businesses and publishers
Search is still the discovery backbone. Alphabet’s 2025 results show search’s resilience and growth as AI features roll out; the pie is getting bigger, not smaller.
Optimize for being cited. When LLMs ground answers, they look for trustworthy, well-structured, crawlable sources. Make sure your pages are indexable and well-labeled so they’re retrieved and cited instead of a forum thread summarizing your work.
Expect new query types. Visual and voice-led searches are growing fast, often incrementally—meaning they’re additions to classic typed searches, not replacements. Prepare your content and product data (images, alt text, schema) to be useful in those contexts.
Quick FAQ
Do LLMs “crawl the web”? No. The applications around LLMs may fetch pages when you ask a question, often via a search partner, but the models themselves don’t operate a global crawler and index like a search engine. Google’s own AI stack explicitly “grounds with Google Search.”
Can I see the web index somewhere? Not directly. You can query it (e.g., with Google or Bing), and if you own a site, you can inspect your pages’ status in Google Search Console or Bing Webmaster Tools.
Isn’t AI going to reduce searches? Evidence to date suggests the opposite: search usage and revenue are growing while AI features roll out, and newer behaviors like Lens are expanding the pie.
So what’s the right mental model? Search engines find and rank facts at web scale. LLMs present and reason over those facts. Together, they produce faster, clearer answers, with links you can check.
The bottom line
LLMs have not replaced search; they’ve changed its surface. Underneath any polished AI answer, the classic information-retrieval pipeline—crawling, indexing, retrieval, and ranking is still doing the heavy lifting. Modern systems combine them: search grounds the answer; the LLM explains it. And if you look at 2025’s numbers and usage patterns, search isn’t going anywhere. It’s evolving, growing, and quietly powering the AI experiences we’re all watching unfold before our eyes. Reach out to SEO Rank Media if you want a partner who understands the direction search is headed and how to position your business to be at the forefront of the evolution.
I recently compared notes with my good friend Nick Eubanks, VP of Owned Media at SEMrush. We aligned on two truths: 1) classic SEO is table stakes; 2) GEO/AEO is now where growth compounds. Nick also shared what his team is seeing on the ground: traffic from LLM-assisted journeys tends to convert better because people use assistants to research and shortlist—so by the time they hit your site, they’re warmer. In one study, conversion rates were ~4.4× higher from LLM traffic vs. traditional organic. Combined with our own client data, the takeaway is clear: being present in AI answers isn’t a vanity metric—it’s a revenue lever. You can view the full video here.
What actually changed (and why you should care)
Under the hood, AI platforms (like Google’s AI Mode) follow a similar pipeline when they search the web: your content is chunked into passages, embedded as vectors (to capture meaning), fetched by high-speed retrieval, filtered by hybrid re-rankers, and then woven into a natural-language answer. If your passages aren’t crystal-clear semantically, they’re less likely to be pulled into that answer layer. Think “optimize for meaning and entities,” not just keywords.
Google has also published sensible basics for the AI era: keep your site crawlable, avoid blocking AI crawlers (Google-Extended, GeminiBot, GPTBot), use clear headings and schema, and ensure what’s in your structured data actually matches what users see. Over-restrictive snippet settings can remove you from summaries entirely.
No, SEO isn’t dead—it’s your eligibility layer
All of the fundamentals still determine whether you’re “in the pool”:
Technical hygiene: sane robots.txt and open sitemaps; don’t block JS/CSS required to render full pages; allow Google-Extended, GeminiBot, and GPTBot.
On-page semantics: precise H1–H3 hierarchy, answer-like formatting, and schema (FAQ/HowTo/Product/Organization). Write in short, extractable passages with concrete stats and full dates.
Internal links & authority: Interlink topic clusters with descriptive anchors; keep building high-quality links and local citations (they’re still a ranking and trust signal, and they feed AI answers).
Think of this as your eligibility layer. Without it, GEO/AEO can’t help you.
GEO/AEO: the layer that gets you retrieved and quoted
Answer engines select passages, not just pages. That means writing “atomic” content—one idea per paragraph, tight sentences, tables or lists where they help, and entity-rich language (use exact names for people, places, and products, minimize pronouns). Each paragraph should stand alone as a mini-answer that a model can lift verbatim.
Two GEO/AEO practices our clients find immediately useful:
Vector validation: Before publishing, embed your draft passages and check similarity against your target questions. Iterate until the cosine similarity is strong (we treat ≥0.85 as a healthy threshold). It’s a quick way to pre-test “retrievability.”
Monitor AI citations: Track when your URLs surface inside Google AI Mode, Perplexity, and ChatGPT. If citations dip, refresh and tighten the affected passages. This is your “share of voice” in AI.
Local & service businesses
Local SEO is currently less affected by AI search engines. When people search in their local area for services, they almost always search on Google, and more specifically the map pack.
People have evolved to use LLMs to research and compare local businesses, so think of AI search optimization as complementary, not primary, for local service-based businesses.
Local also remains a smart place to invest because the evidence LLMs prefer—real reviews, practitioner bios, photos, and third-party citations—maps cleanly to what local SEO already does well.
Assistants won’t just list options; they’ll recommend one provider and explain why. Help them help you:
Fortify proof: Showcase review excerpts, credentials, and outcomes as short, quotable blocks.
Citations & consistency: Keep your NAP data clean and expand high-relevance local citations; it improves Maps visibility and gives answer engines more reliable signals to quote.
Watch GA4 and Search Console, but with added context: impressions and AI citations often lead the way; raw CTR can be misleading when assistants satisfy the query in-place.
What to do next (simple, high-impact moves)
You don’t need a full overhaul to benefit from GEO/AEO. Start here:
Open the gates: sanity-check robots.txt and server logs; allow Google-Extended, GeminiBot, and GPTBot; keep XML/RSS feeds current.
Make content “answer-able”: give each H2 a direct ≤80-word answer, then details. Use tables/lists for facts and include full dates.
Strengthen semantics: ensure one topic per page, clean H1–H3, and add relevant schema (FAQ/HowTo/Product/Organization).
Validate vectors: quickly test your top five money pages for cosine similarity against priority questions; revise ambiguous phrasing.
Distribute beyond your site: publish the same answers (adapted) across formats—web, video, and communities—because LLMs cite the whole web, not just your domain. For example, studies show that Reddit is a place that AI search engines love to quote from.
Will traditional SEO fade away?
Not in the next five or ten years. People will always compare, verify, and buy; what’s changed is the quality bar and the interface. In our clients’ data and in my conversation with Nick, the brands winning AI placements combine (a) clean technical SEO and authoritative content with (b) GEO/AEO practices that make them more likely to be cited in AI searches. That’s the new landscape for 2025-2026.